

You have three teams, three boards, a release spanning all of them, and a stakeholder asking for a date. So you add up each team's capacity, divide the backlog by it, and give an answer. Then the date slips anyway.
The problem usually isn't the arithmetic. A capacity plan and a delivery forecast answer different questions: capacity planning tells you how much availability your teams have, In contrast, forecasting tells you what that availability has historically turned into. This article covers the second half , which is turning delivery history in Jira into a forecast you can defend. In practice, a more reliable cross-team forecast rests on four things: comparable historical delivery data, a clearly defined Jira scope, explicit allocation assumptions, and probability ranges instead of a single promised date. The availability side is a discipline of its own: dedicated capacity planning tools track PTO, holidays, part-time allocation, and people shared across several teams — the inputs native Jira has no view of.
What industry research says about delivery predictability
Delivery forecasts are shaped by uncertainty and complexity — factors that traditional planning methods often underestimate. Bent Flyvbjerg’s research on large-scale projects shows that the vast majority exceed their original budget, schedule, or both, with IT projects among the worst performers. PMI’s Pulse of the Profession consistently finds that complexity, dependencies, and poor visibility into progress are the leading causes of delivery failure. These studies describe general delivery risk across industries and project types . They do not predict outcomes for a specific Jira release.
A single promised date hides exactly the uncertainty these patterns describe. It collapses a range of possible outcomes into one number that feels precise but is not.
For software teams specifically, practitioners like Daniel Vacanti and Troy Magennis have developed a more evidence-based alternative. Vacanti’s work on flow metrics argues that useful forecasts begin with historical throughput data and explicit acknowledgment of variability — not ideal-day estimates. Magennis, in his writing on probabilistic forecasting, demonstrates how Monte Carlo simulations turn that variability into probability ranges: instead of “we’ll finish on March 15,” a team can say “there’s an 85% chance we’ll finish by March 15.”
This is the foundation for the Jira workflow that follows: historical delivery data, visible assumptions, and forecasts expressed as ranges rather than false certainties.
Capacity plans are assumptions — forecasts need evidence
"Team B is 80% available next quarter" is a statement about input. It says nothing about output until you know what that team has done with its available time before. Two teams can be equally available and deliver very differently, because the gap between planned capacity and observed delivery is filled with things a capacity model doesn't see: dependencies, interruptions, mid-sprint scope change, and teams running on different cadences.
Jira does report on delivery. It ships a Sprint Report, a sprint Burndown Chart, a Velocity Report, a Burnup chart, and a Release Burndown — and each is a reasonable record of what happened. What Jira doesn't provide out of the box is a single, availability-aware view that forecasts across several teams at once: every native report answers one question, for one board, in one time box.
What native Jira reports do — and where they stop
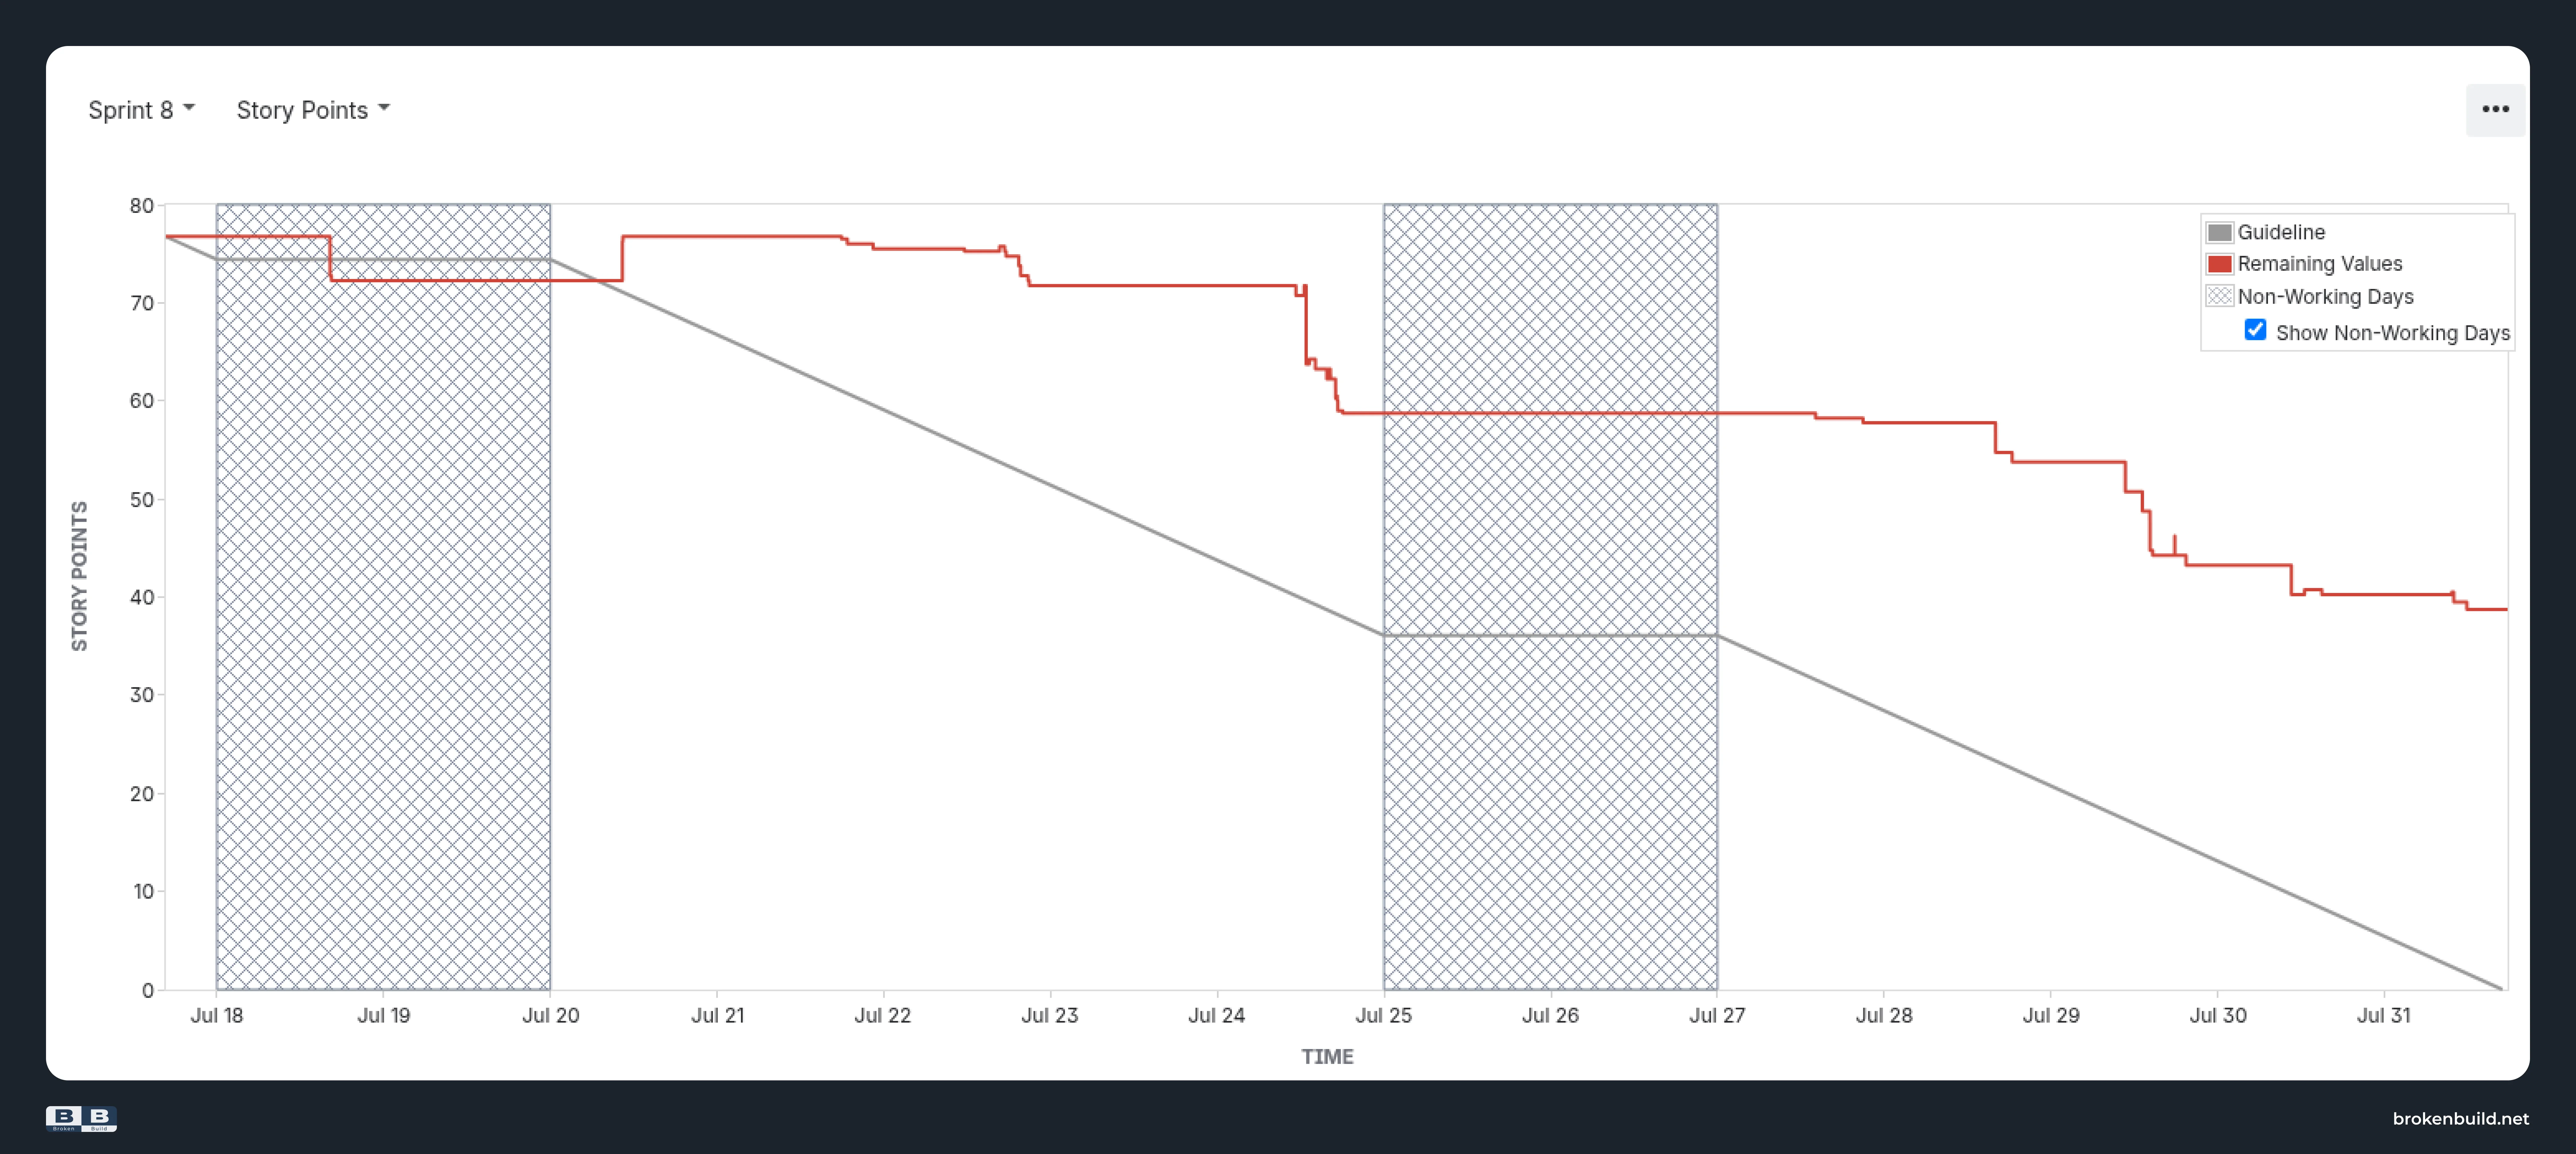
Scope: One sprint, one Scrum board
Limitation: The Guideline is drawn from the sprint’s starting estimate down to zero — it describes the plan, not what the team has historically delivered.
- Velocity Report
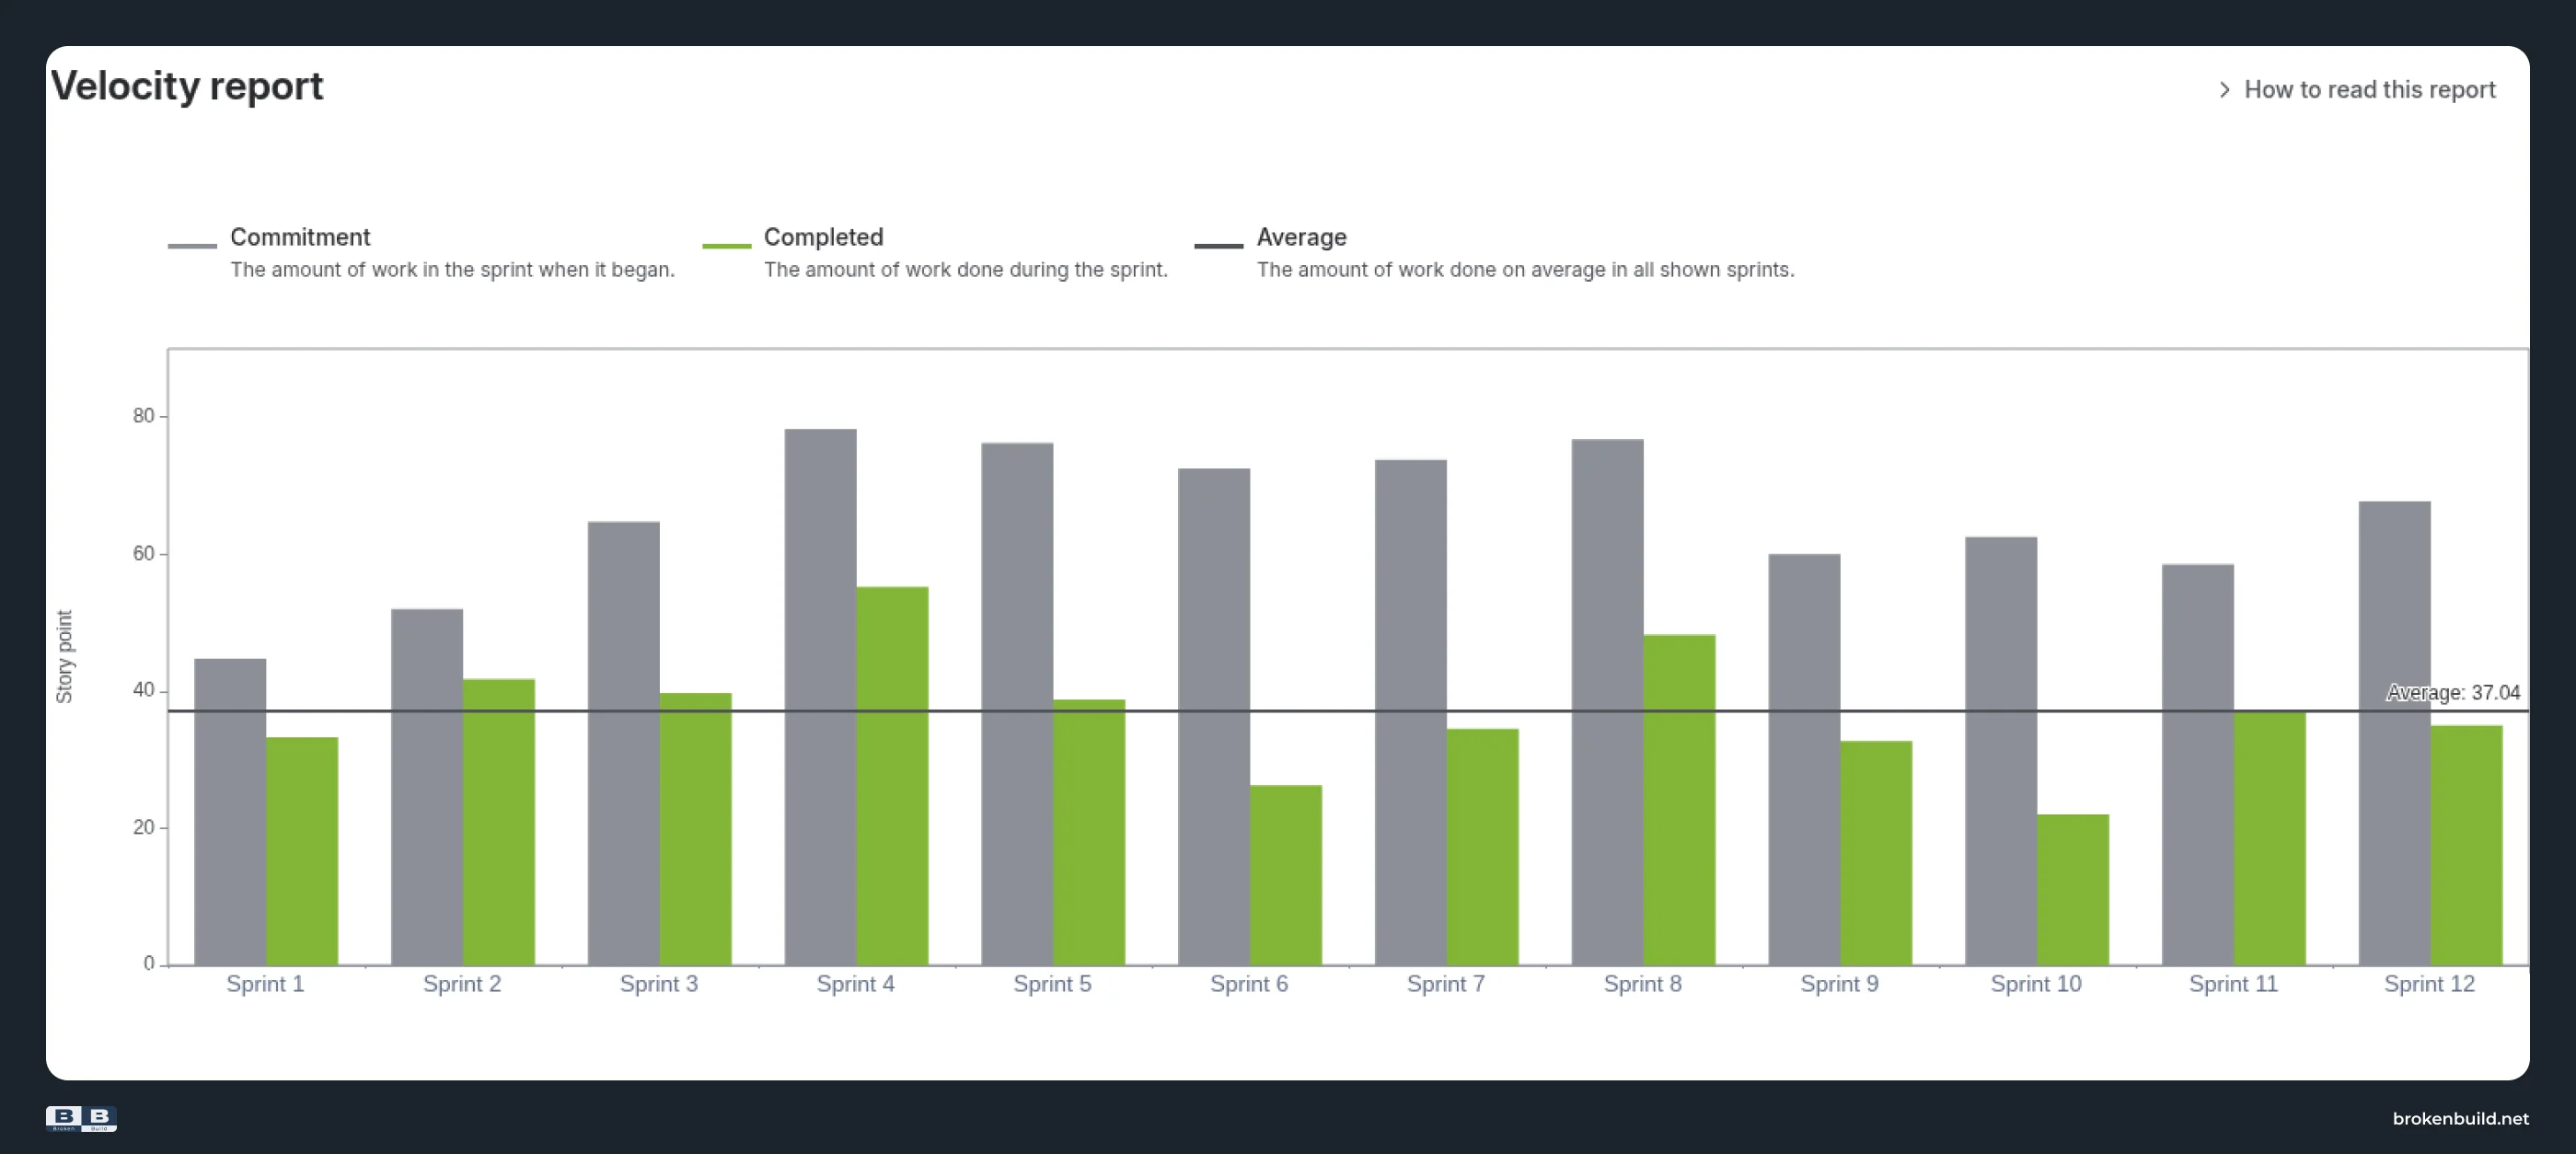
Scope: One Scrum board, a fixed window of past sprints.
Limitation: Shows commitment, completed, and an average — nothing that explains a miss, and no way to compare teams.
- Release Burndown
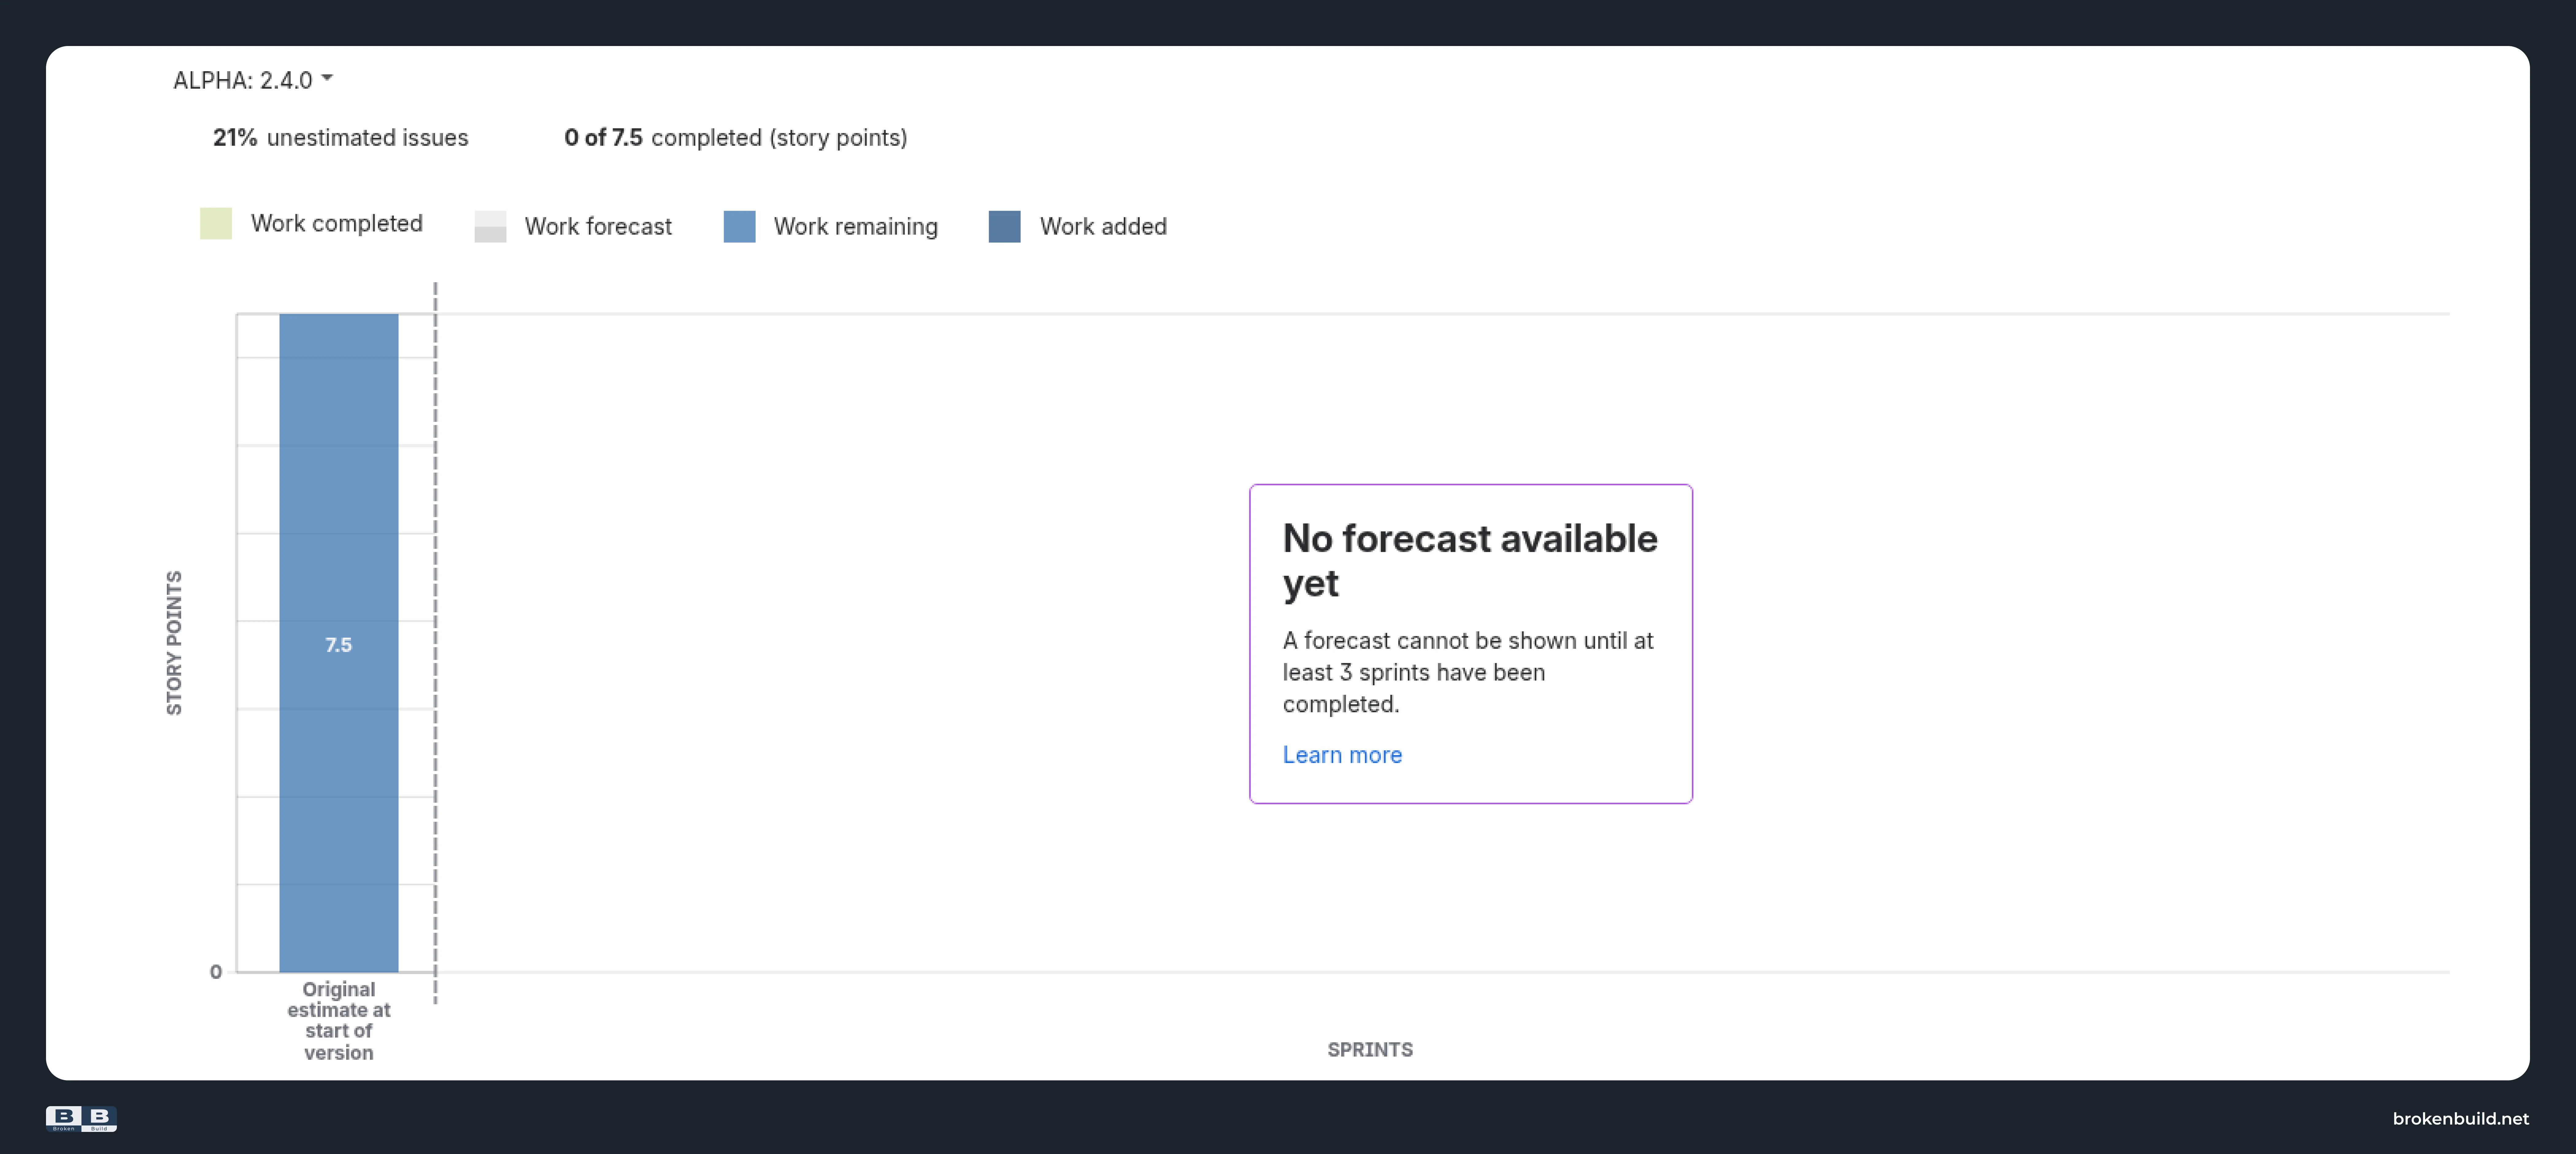
Scope: One release, one board, Scrum only.
Limitation: Velocity is hard-coded to the last three sprints, with exactly one scenario — and nothing renders until three sprints have closed.
None of the five reads a Kanban board, spans more than one board, or knows that Team B is only 80% available next quarter. Turning that history into an actual forecast — one with a range and a confidence level attached — is what Agile Burnup Burndown Charts is built for.
So start by making the availability assumption explicit. TimePlanner provides a shared planning view of work, leave, holidays, part-time allocation, and people shared across several teams — so "80% available" becomes a number someone stands behind rather than a guess. That's an assumption worth testing against delivery history.
Start with what your teams have actually delivered
The average is a useful baseline, but it shouldn't stand on its own. If a team's last six sprints were 18, 31, 12, 27, 22, and 29 story points, the average is 23 — and the spread around it is what tells you how much confidence that 23 deserves.
The simplest approach: use your own team's delivery history as the velocity baseline. This assumes you have enough comparable history to trust. But a new team, a recent reshuffle, or a quiet quarter can leave you without enough comparable data — and native Jira has no built-in way to base a forecast on a different, comparable scope.
When that happens, you can choose a comparable board, project, release, epic, initiative, or custom JQL filter as your reference history. The key question: is it actually comparable? Different teams with different cadences, scope types, and constraints show very different velocities. Using velocity from a maintenance board to forecast a new feature initiative will produce a forecast that sounds confident but is unreliable.
Before you use alternative history, verify it's comparable using the benchmarking approach covered in the "Configure the forecast model" section below.
Make the forecast reflect the real delivery scope
Cross-team delivery rarely maps onto "one board, one sprint". Agile Burnup Burndown Charts build the chart on one kind of data source (1) at a time — Scrum boards, Kanban boards, projects, releases, initiatives, epics, saved filters, or custom JQL — but on as many of that kind as you need. A release spanning three boards is one chart, not three you reconcile by hand.
Health tiles (2) above it show % completed, scope change per sprint, and unestimated work. The burndown view (3) plots remaining work against total scope, so scope that arrives mid-flight shows up as a line that refuses to fall — which is exactly the failure this article is about.
See it live: Cross-team burndown chart
Find out why you're behind
Seeing that you are behind is the easy part; the Breakdown is where you find out why. Click a past interval (1), open the Breakdown (2), and find Completed work and Scope change broken down by board, project, issue type, or any other dimension (3). The Issue list (4) underneath goes one level further — down to the specific work items behind each number.


Configure the forecast model
When you forecast, three things drive the outcome: the velocity baseline (where the projection gets its historical throughput), remaining work, and scope growth (new work arriving while you deliver). This section covers how to set each one.
Remaining work: value and growth separately
Remaining work is two settings, not one. The value (1) is what the forecast burns down — the auto figure from your current scope, a what-if number, an epic estimate, or a JQL filter. Growth (2) is separate: it models new work arriving while you deliver, at the observed average, at a what-if number, or none at all. Teams that work in reporting intervals rather than sprints read both per interval instead.
Verify alternative velocity is comparable
If you're using alternative history as your velocity baseline (see "Start with what your teams have actually delivered"), verify it's actually comparable before you use it. The Benchmarking velocity chart in Agile Velocity Charts puts each team on its own bar and overlays reference points across all of them — average, median, 25th and 75th percentile — which is what turns "is this board a reasonable source of throughput for our forecast?" into an answerable question. It is not an invitation to add or average raw velocities across teams: story points are a local unit, so the reference history has to be comparable to begin with, or expressed in a common metric — Story Points, Issue count, Original estimate, or Time spent.
See it live: Benchmarking velocity chart
Apply alternative throughput to your forecast
The alternative throughput data changes one thing only: where the forecast gets its history. Completed work, remaining work, and scope change still describe the release you are tracking — only the throughput feeding the projection comes from elsewhere: a comparable board, project, release, epic, initiative, or JQL scope.
Below, the forecast runs on a comparable board's last six sprints — 61, 28.5, 27, 35.5, 41, and 0 story points — while the chart itself still tracks the same cross-team scope.
This is useful when you don't have enough comparable history of your own. Choose the reference carefully — verify it with benchmarking above — then carry that assumption explicitly into your forecast configuration.
Establish real availability before forecasting
A forecast multiplies delivery history by an availability assumption, and that assumption is usually the weakest number in the room. Native Jira has no view of it: it does not know who is on leave next month, who works part-time, or who is shared across three teams.
That is the gap a capacity planning tool fills. TeamBoard TimePlanner puts people, planned work, leave, holidays, and workload on a single schedule, and reports utilisation against capacity for each person. The 80% in your forecast stops being a figure someone defended in a meeting and becomes an indicator with a source behind it.
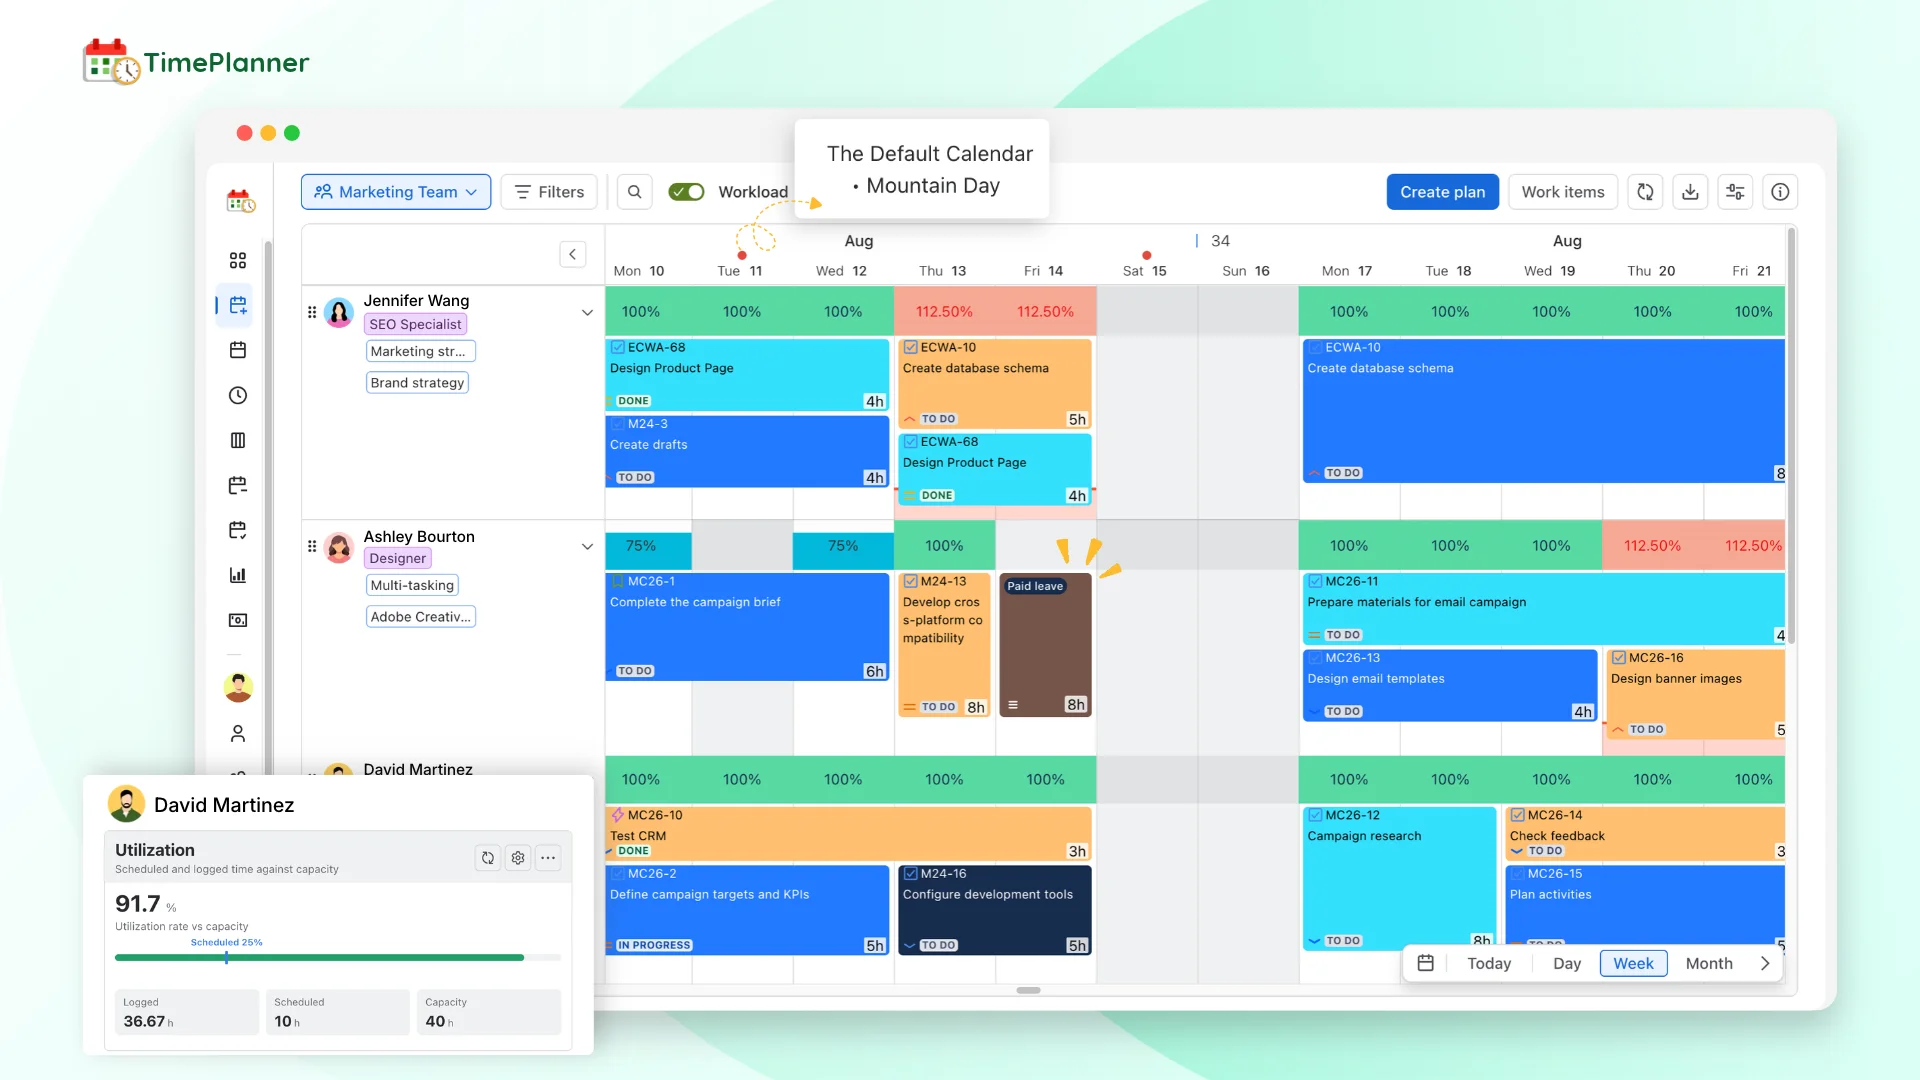
Once those availability assumptions are explicit, they can be applied to the forecast — which is what the capacity allocation coefficient below does.
Model partial team allocation in the forecast
Teams are almost never 100% on one thing. The capacity allocation coefficient applies that to the forecast, multiplying forecast velocity by the share of capacity you expect on this scope. In the cross-team burndown below, set the capacity allocation coefficient to 80% (1). The forecast table shows how velocity is adjusted — for example, 79.2 × 80% = 63.36 (2) — and the resulting completion shifts to 8 sprints (3).
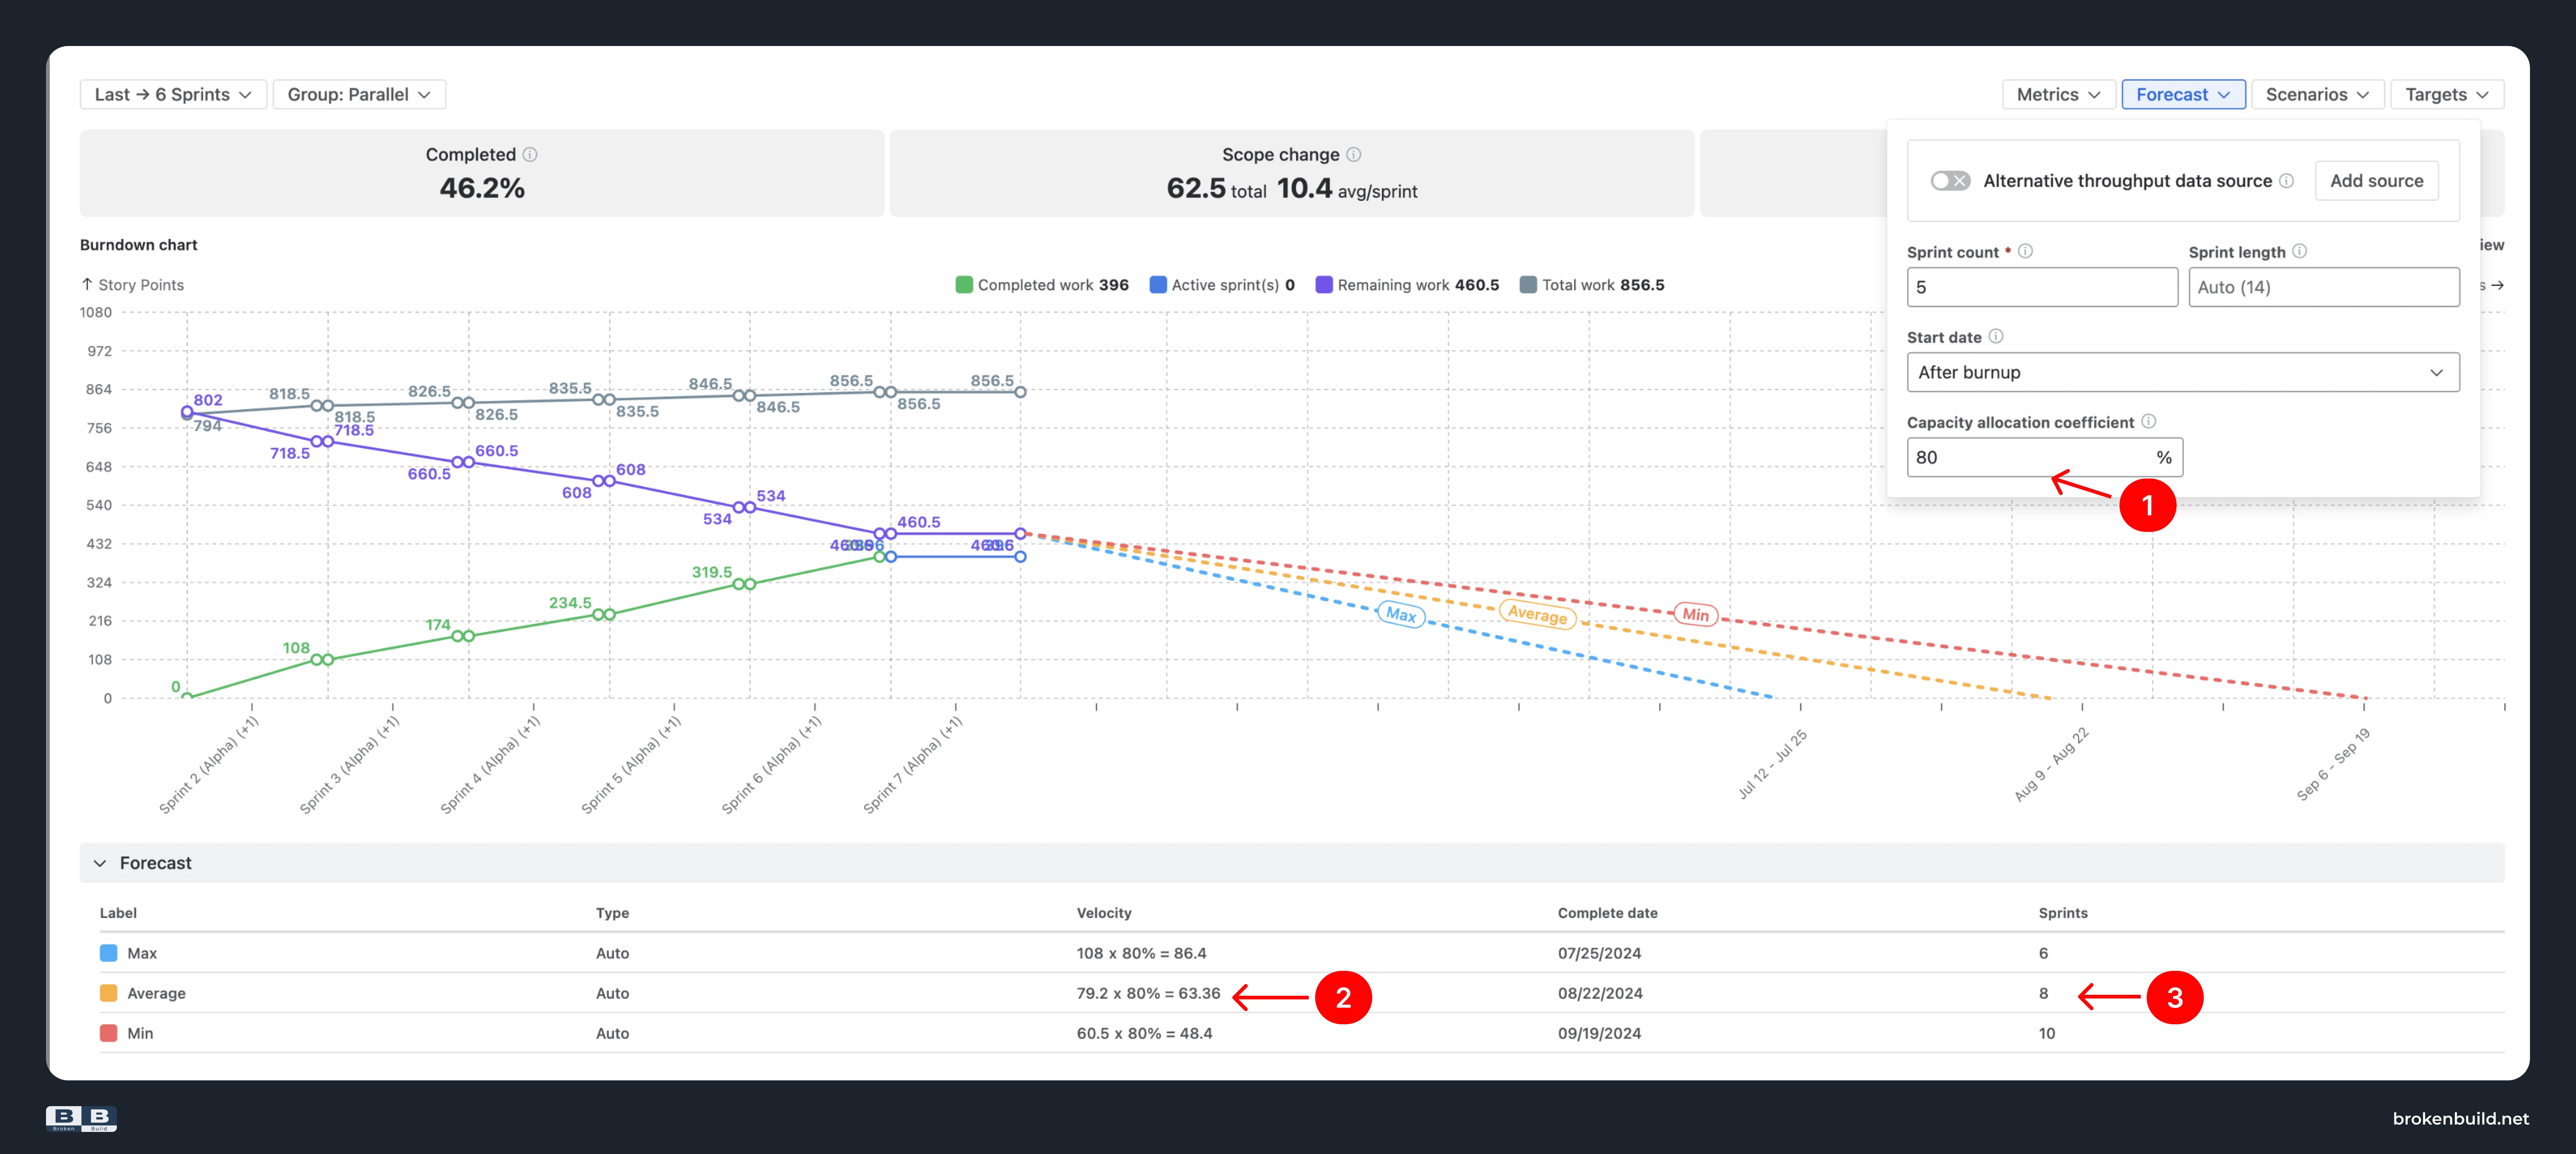
This turns an argument into a comparison. Instead of debating whether a team is "mostly" on the release, run the forecast at 50%, 80%, and 100% of capacity. If 60% and 80% land in the same sprint, the question doesn't matter. If they're six weeks apart, you've found the decision that actually drives the release date.
Two things to be precise about: the coefficient is a team-level multiplier on historical delivery, so it doesn't know a specific engineer is on leave in week three. That's the seam between the two tools — you read the availability percentage in TimePlanner and enter it in the chart yourself; nothing passes between them automatically. And an allocation is an assumption, not a guarantee. Writing 80% into the chart doesn't make it true; it makes it explicit and reviewable against what actually happened.
Replace one promised date with a set of delivery scenarios
"Done in six sprints" is the most confident and least useful answer you can give. Variability compounds across teams, so a single point estimate can create false confidence and hide how much the actual outcome may vary.
Beyond those default scenarios, Agile Burnup Burndown Charts let you layer what-if forecasts on the same chart: target date, target velocity, velocity percentile (P50, P75, P85 of past velocities), and Monte Carlo probability. Monte Carlo runs 100,000 simulations, drawing randomly from past velocities, and reports the date by which a chosen percentage of those runs complete — in the documented example, 80% probability lands on 14 February 2026.
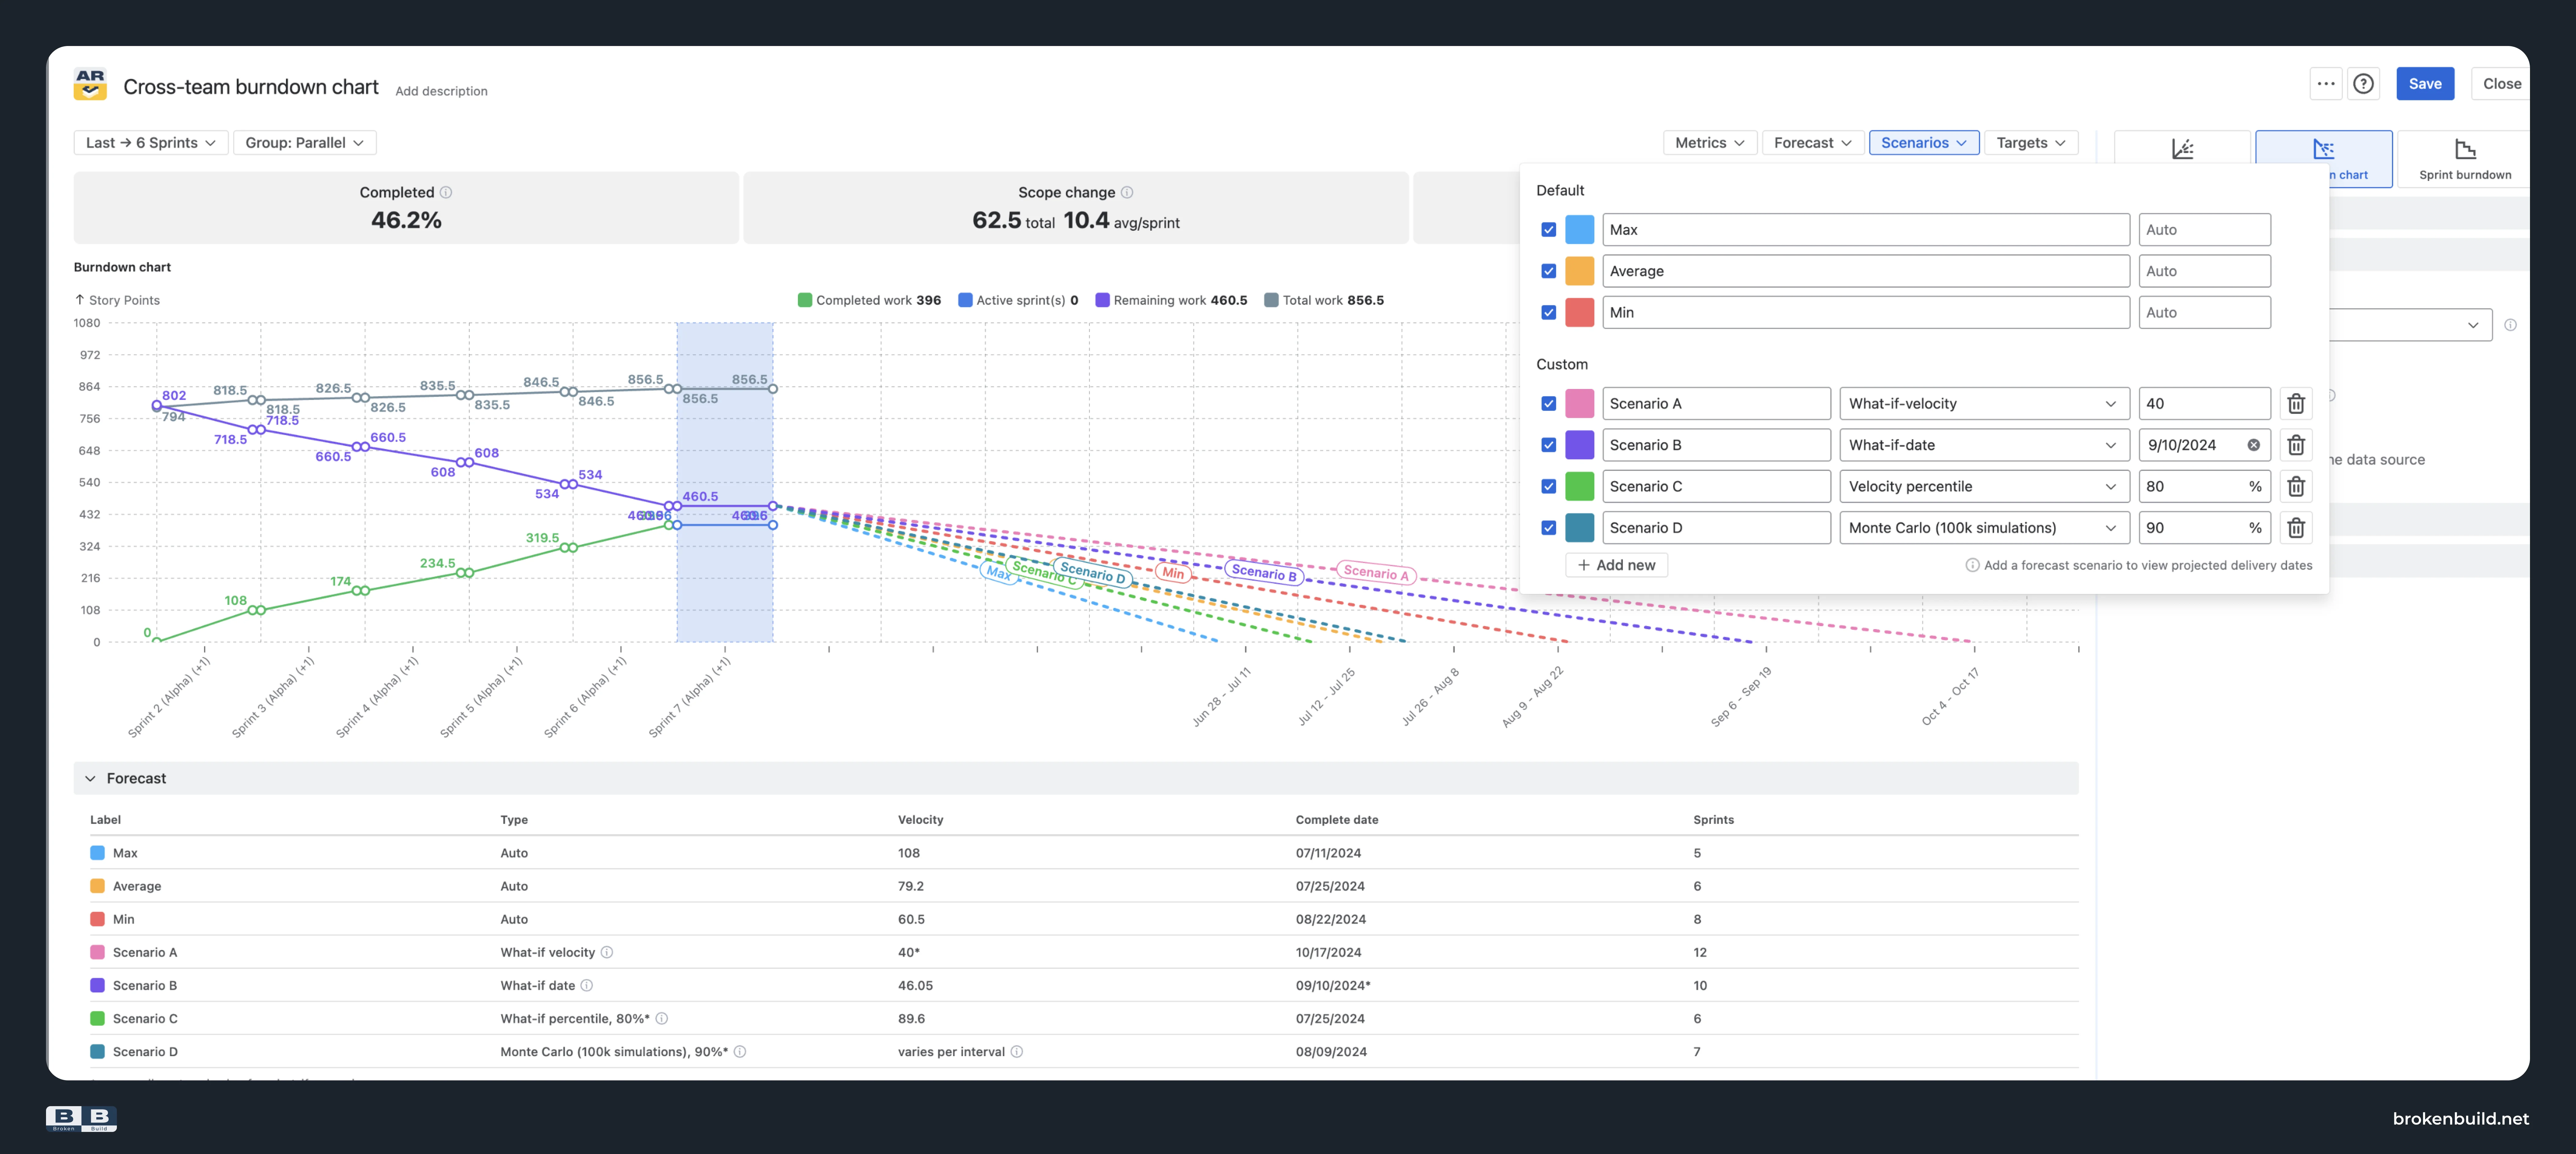
For teams that want Monte Carlo as a dedicated view, Agile Monte Carlo Charts answers the question from both directions. The When chart estimates when remaining work will finish; the How many chart estimates how much scope will be done by a fixed date. Both show confidence lines at 50%, 85%, 95%, or a custom percentile — pick the one that matches the conversation: P50 for internal sequencing, P85 for commitments you'll be held to, P95 when missing the date carries contractual weight.
Naming the confidence level out loud is most of the value — "85% confident by 14 February" invites a real discussion about scope and risk in a way that "mid-February" never does.
See it live: Monte Carlo forecasting chart for Scrum
A practical workflow for cross-team delivery forecasting
- Establish the availability assumptions per team. Use TimePlanner to work them out, then carry the resulting percentage into Broken Build’s forecast settings by hand in step 3.
- Select the Jira scope and historical window — the release, board, initiative, epics, or JQL that defines the commitment.
- Apply the expected capacity allocation. Where teams differ a lot, forecast them separately rather than blending them into one average.
- Review scenarios and confidence ranges, then attach a probability to the date you'll communicate.
- Investigate the breakdown behind the forecast. A forecast you can't explain won't survive its first challenge in a steering meeting.
- Compare planned versus actual next cycle and feed the gap back into step 1.
Example: from availability assumptions to a forecast you can defend
Illustrative scenario — numbers are for demonstration only.
A release spans three teams. In TimePlanner, you establish that Team A is fully assigned, Team B is 60% available (shared with another initiative), and Team C is blocked on an integration Team A owns.
In Agile Burnup Burndown Charts, create a combined burndown across all three boards. Set the capacity allocation coefficient to reflect the overall expected availability — for example, 80% if that represents the weighted average. The Breakdown shows each team's contribution to the total.
For team-specific analysis, create separate charts with their own allocation coefficients: Team A at 100%, Team B at 60%. Team C's constraint is sequencing, not capacity — the Breakdown and dependency view reveal this better than an allocation adjustment.
The outcome isn't "the release lands on 12 March." It's: "At current allocations, we're 85% confident by late March. The biggest lever is Team C's dependency — clear it and the date could move in by two sprints." That's a forecast someone can act on.
Two halves of the same plan
Reliable cross-team planning needs two inputs that are easy to confuse: visibility into availability and evidence from actual delivery. A capacity plan without delivery history is an assumption with a decimal point. Delivery history without availability context explains the past but gives you no basis for projecting it forward.
TimePlanner helps teams make planned work, leave, holidays, part-time allocation, and workload visible. Broken Build then applies those availability assumptions to Jira delivery data, scope, and forecast scenarios. Depending on the forecasting method, the result can include scenario ranges or probability-based confidence levels. If the availability side is where your planning tends to break down, see the companion piece: How to Plan Capacity Across Multiple Teams When Work Spans Several Boards.
For the forecasting side, explore Agile Burnup Burndown Charts and Agile Monte Carlo Charts on the Atlassian Marketplace. Several charts in this article also have interactive examples you can open without installing anything. All apps mentioned in this article — Agile Velocity Charts, Agile Burnup Burndown Charts, and Agile Monte Carlo Charts — are available as standalone apps and as part of the Agile Reports and Gadgets bundle.
Explore the examples